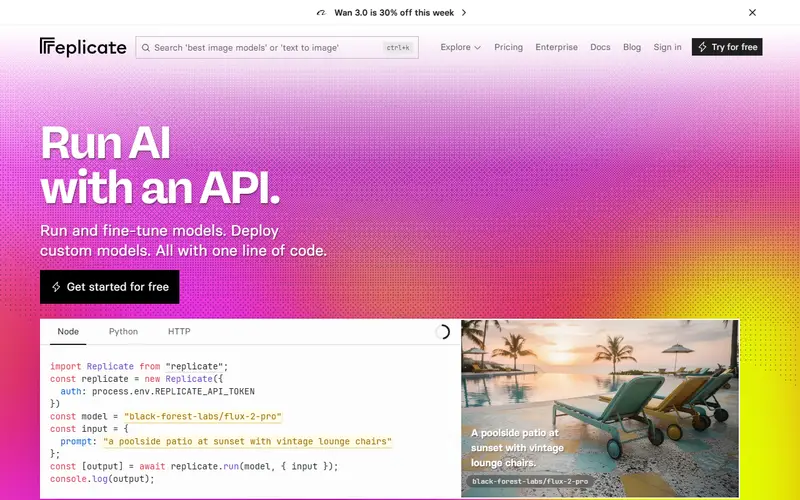
Overview
Replicate is an API for running AI models that other people have published, plus your own. The catalogue leans toward generative media: image models such as FLUX, Nano Banana, gpt-image and Seedream, video models such as Wan, and speech and music models, alongside some LLMs. Each model page shows an estimated cost per run.
There are two billing styles. Most public models charge for the seconds of hardware they use, from $0.81 an hour on a T4 to $5.49 an hour on an H100. Official models, maintained with their creators, charge per output instead: $0.04 per FLUX Pro image, or $3.75 per million input tokens for DeepSeek R1. Private deployments of your own models bill for all uptime, including idle time, unless they are fast-booting fine-tunes.
You can try select models free before Replicate asks for billing details, then choose prepaid credit or monthly billing in arrears. Replicate may charge early the first time usage crosses certain thresholds, as a fraud check.
Pricing and plans
| Plan | Price | What you get |
|---|---|---|
| CPU (small) | $0.09/hr | $0.000025 per second |
| Nvidia T4 | $0.81/hr | $0.000225 per second |
| Nvidia L40S | $3.51/hr | $0.000975 per second |
| Nvidia A100 (80 GB) | $5.04/hr | $0.0014 per second |
| Nvidia H100 | $5.49/hr | $0.001525 per second |
| FLUX Pro (official) | $0.04 per image | FLUX Schnell $3 per 1,000 images |
| DeepSeek R1 (official) | $3.75 in / $10 out per 1M | Output listed as $0.01 per 1,000 tokens |
What it does
- Large model catalogue
- Public image, video, audio and language models callable with one API.
- Official models
- Maintained models billed per image, per video second or per token instead of per second of GPU.
- Custom deployments
- Deploy your own or fine-tuned models; fast-booting fine-tunes bill only while running.
- Per-second billing
- Public models charge by hardware time, from $0.000025 per second on small CPUs.
- Prepaid or arrears billing
- Buy credit up front or pay monthly for the previous month's usage.
Strengths and limitations
Strengths
- Broad choice of image, video and audio models behind one API.
- Per-output pricing on official models makes costs easy to estimate.
- No GPU management for running open models.
Limitations
- Per-second billing on community models makes cost depend on model speed and cold starts.
- Private deployments bill for idle time as well as active time.
- The free allowance is small and not quantified.
- LLM prices can be higher than specialist token providers (DeepSeek R1 at $10 per 1M output tokens).
Who it suits
Good for
- Apps that generate images, video or audio
- Trying many community models quickly
- Serving a fine-tuned image model without running GPUs
Look elsewhere if
- High-volume text generation, where token-priced LLM providers cost less
- Always-on private deployments on a tight budget
Alternatives to Replicate
| Tool | From | Free option | Stages |
|---|---|---|---|
| GroqCloud Inference provider (open-weight models) | Usage-based | Free tier | |
| Gemini API AI model API (model maker) | Usage-based | Free tier | |
| Mistral API (Mistral Studio) AI model API (model maker) | Usage-based | Free tier | |
| Scaleway Generative APIs Inference provider (EU-hosted open-weight models) | Usage-based | ||
| OpenRouter Model router (unified API) | — | Free tier | |
| DeepInfra Inference provider (open-weight models) | Usage-based |
Questions
Is Replicate free?
You can run select models free for a while, after which Replicate asks you to set up billing. There is no ongoing free tier.
How does Replicate charge for models?
Most public models are billed by the second of hardware time; official models are billed per output such as per image or per token.
How much does an H100 cost on Replicate?
$0.001525 per second, about $5.49 per hour, on 2026-09-29.
Sources read for this page