Overview
DeepInfra is an inference provider focused on low prices for hosted models. It lists more than 100 models, mostly open-weight families such as DeepSeek, Llama, Qwen, Mistral, Kimi and NVIDIA Nemotron, and a few proprietary ones, all behind an OpenAI-compatible API. It also rents GPUs by the hour.
Small and mid-size models are very cheap here: Mistral Nemo at $0.019 in and $0.03 out per million tokens, DeepSeek-V4-Flash-0731 at $0.06 / $0.18 with $0.015 cached input, and Llama 3.3 70B Turbo at $0.10 / $0.32. The homepage often runs time-limited discounts on specific models.
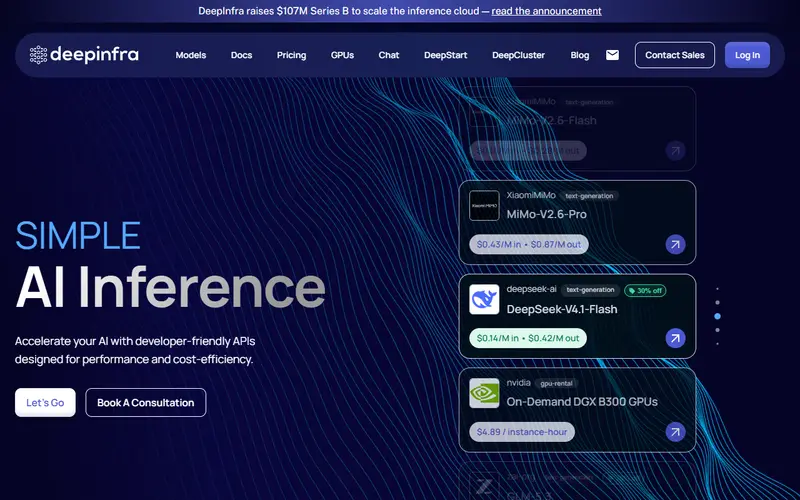
There is no free tier: you must add a card or prepay. Prepaid balances draw down as you go; invoiced accounts are billed monthly. A spending limit can be set in the dashboard, and DeepInfra states a zero-retention policy for inputs and outputs. Temporary discounts shown on the homepage on 2026-09-29, such as 30% off DeepSeek-V4.1-Flash and 61% off MiMo-V2.5-Pro, are not reflected in the list prices recorded here, so check the model page for the price you will pay.
Pricing and plans
| Plan | Price | What you get |
|---|---|---|
| Mistral-Nemo-Instruct-2407 | $0.019 in / $0.03 out per 1M | Serverless |
| DeepSeek-V4-Flash-0731 | $0.06 in / $0.18 out per 1M | Cached input $0.015 |
| Llama-3.3-70B-Instruct-Turbo | $0.10 in / $0.32 out per 1M | Serverless |
| Claude-Sonnet-5 | $3 in / $15 out per 1M | Proprietary model listed on DeepInfra's pricing page |
| GPU rental | Per hour | On-demand GPUs including DGX B300 |
What it does
- Large open-model catalogue
- 100+ models across text, embeddings and other tasks.
- Spending limit
- Set a cap in the dashboard to avoid unexpected charges.
- Prepaid or invoiced
- Draw down a prepaid balance or receive a monthly invoice.
- Zero retention
- DeepInfra states it does not retain inputs or outputs.
- GPU rental
- On-demand GPUs including NVIDIA DGX B300 for custom workloads.
Strengths and limitations
Strengths
- Low per-token prices on small and mid-size open models, e.g. Llama 3.3 70B Turbo at $0.10 / $0.32.
- Spending limit and prepaid option keep costs bounded.
- Stated zero-retention policy for inputs and outputs.
Limitations
- No free tier; a card or prepayment is needed before first use.
- Frequent promotional prices make it harder to predict the long-run rate.
- No EU region or compliance certifications were found on the pages read.
Who it suits
Good for
- High-volume, cost-sensitive tasks on open models
- Embedding and classification pipelines
Look elsewhere if
- Teams needing formal compliance documentation up front
- Projects that need a free allowance
Alternatives to DeepInfra
| Tool | From | Free option | Stages |
|---|---|---|---|
| Mistral API (Mistral Studio) AI model API (model maker) | Usage-based | Free tier | |
| OpenRouter Model router (unified API) | — | Free tier | |
| Gemini API AI model API (model maker) | Usage-based | Free tier | |
| GroqCloud Inference provider (open-weight models) | Usage-based | Free tier | |
| Replicate Model hosting API (image, video, audio and LLMs) | $0.09/hr | ||
| Scaleway Generative APIs Inference provider (EU-hosted open-weight models) | Usage-based |
Questions
Does DeepInfra have a free tier?
No free tier was listed on 2026-09-29; DeepInfra says you have to add a card or prepay to use the service.
Can I cap my DeepInfra spend?
Yes. DeepInfra lets you set a spending limit, and prepaid accounts only draw down their balance.
How much does DeepSeek V4 Flash cost on DeepInfra?
DeepSeek-V4-Flash-0731 was $0.06 per 1M input tokens ($0.015 cached) and $0.18 per 1M output tokens on 2026-09-29.
Sources read for this page