Overview
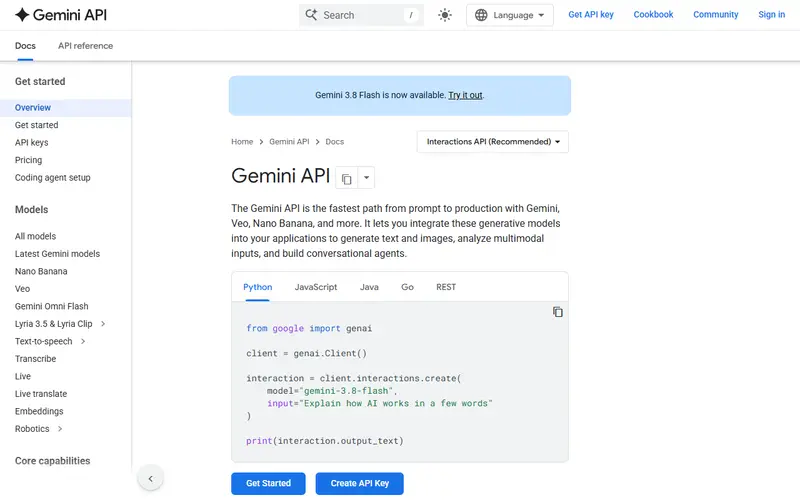
The Gemini Developer API is Google's direct API for Gemini, separate from Vertex AI on Google Cloud. You get a key in Google AI Studio and can start on the free tier, which covers most current Flash, Flash-Lite, speech and Live models. Google states that free-tier content is used to improve its products; paid-tier content is not.
Paid pricing is per million tokens and varies by mode: Standard, Batch and Flex (both about half price) and Priority (about 1.8x). The newest Flash models (3.6, 3.7 and 3.8) are on introductory pricing of $0.75 in and $3.75 out until 31 December 2026, doubling from 1 January 2027, which matters if you are budgeting next year.
Paid accounts move through tiers that each carry a monthly spend cap and a rolling 10-minute spend limit, starting at $250 a month once a billing account is linked. New billing starts on prepaid credit before moving to pay-as-you-go. Exact free-tier rate limits are no longer listed in the docs; check the rate-limit page in AI Studio for your project.
Pricing and plans
Free tier
Free input and output tokens on most Flash, Flash-Lite, TTS and Live models (not Gemini 3.1 Pro Preview), with rate limits shown per project in Google AI Studio.
At the limit Not stated The vendor does not say what happens at the limit, or we have not found it yet.
| Plan | Price | What you get |
|---|---|---|
| Free | $0 | Limited models; content used to improve Google's products |
| Gemini 3.8 Flash | $0.75 in / $3.75 out per 1M | Introductory to 2026-12-31; $1.50 / $7.50 from 2027-01-01 |
| Gemini 3.5 Flash-Lite | $0.30 in / $2.50 out per 1M | Free tier available |
| Gemini 3.1 Flash-Lite | $0.25 in / $1.50 out per 1M | Text/image/video input price; audio input costs more |
| Gemini 3.1 Pro Preview | $2 in / $12 out per 1M | Prompts up to 200K tokens; $4 / $18 above; no free tier |
| Batch / Flex | 50% off | e.g. Gemini 3.8 Flash batch at $0.375 / $1.875 |
| Enterprise | Custom | Through Gemini Enterprise Agent Platform: provisioned throughput, volume discounts |
What it does
- Free tier
- Free input and output tokens on most Flash, Flash-Lite, TTS and Live models, rate-limited per project.
- Batch and Flex
- Half-price asynchronous or lower-priority processing on paid tiers.
- Context caching
- Cached input at about a tenth of the input price plus an hourly storage fee per 1M tokens.
- Grounding
- Google Search and Maps grounding with 5,000 free requests per month on paid tiers, then $14 per 1,000.
- Spend caps
- Tier-based monthly caps ($250, $2,000, $20,000+) and 10-minute spend limits.
- Multimodal models
- Text, image, audio, video input plus TTS, live audio, transcription and image-generation models.
Strengths and limitations
Strengths
- An ongoing free tier on current Flash models, not just one-off signup credit.
- Low paid prices on Flash-Lite models ($0.25 to $0.30 per 1M input tokens).
- Spend caps and 10-minute spend limits on paid tiers limit runaway costs.
- Batch and Flex halve prices for non-urgent jobs.
Limitations
- Free-tier prompts and responses are used to improve Google's products.
- Gemini 3.1 Pro Preview and image models have no free tier.
- Introductory Flash prices double on 2027-01-01.
- Exact free-tier rate limits are not published in the docs, only in AI Studio.
- Tier 1 accounts are capped at $250 a month until they have paid $100 and waited 3 days.
Who it suits
Good for
- Prototypes and hobby projects that need a free model API
- Multimodal apps handling images, audio or video
- High-volume, low-cost tasks on Flash-Lite
Look elsewhere if
- Free-tier use with confidential data (content is used to improve Google's products)
- Enterprises needing contracts, regional control and provisioned throughput (use Vertex AI)
Pricing history
-
Gemini 2.5 limited to existing users
Announced 2026-09-18: access to Gemini 2.5 models is limited to active users; Google recommends newer models for new projects. Source ↗
-
Gemini 3.7 Flash launched at introductory price
Announced 2026-08-13: Gemini 3.7 Flash at $0.75 in / $3.75 out per 1M tokens through 2026-12-31; the pricing page lists $1.50 / $7.50 from 2027-01-01 for 3.6, 3.7 and 3.8 Flash. Source ↗
-
Gemini 2.0 Flash shut down
Effective 2026-06-01: Gemini 2.0 Flash models were shut down; Google directs users to Gemini 3.5 and 3.1 models. Source ↗
-
Gemini Flex and Priority tiers
Announced 2026-04-01: new Flex (about half price, lower priority) and Priority (higher price) inference tiers alongside Standard and Batch. Source ↗
-
Gemini API prepay and postpay billing
Announced 2026-03-23: Prepay and Postpay billing plans launched in Google AI Studio, affecting existing accounts; billing now starts prepaid before moving to pay-as-you-go. Source ↗
-
Gemini Batch Mode launched
Launched 2025-07-07: asynchronous Batch Mode for the Gemini API, now priced at 50% of standard rates on paid tiers. Source ↗
Alternatives to Gemini API
| Tool | From | Free option | Stages |
|---|---|---|---|
| DeepInfra Inference provider (open-weight models) | Usage-based | ||
| Scaleway Generative APIs Inference provider (EU-hosted open-weight models) | Usage-based | ||
| GroqCloud Inference provider (open-weight models) | Usage-based | Free tier | |
| Replicate Model hosting API (image, video, audio and LLMs) | $0.09/hr | ||
| OpenRouter Model router (unified API) | — | Free tier | |
| Mistral API (Mistral Studio) AI model API (model maker) | Usage-based | Free tier |
Questions
Is the Gemini API free?
There is a free tier covering most Flash, Flash-Lite, speech and Live models, with per-project rate limits shown in AI Studio. Pro Preview and image models are paid only.
Does Google train on Gemini API free tier data?
Google's pricing page says free-tier content is used to improve its products, and paid-tier content is not.
How much does Gemini 3.8 Flash cost?
$0.75 per 1M input tokens and $3.75 per 1M output tokens through 31 December 2026, then $1.50 and $7.50 from 1 January 2027.
What is the difference between the Gemini API and Vertex AI?
The Gemini API is Google's developer API through AI Studio with a free tier; Vertex AI (now Agent Platform) is the Google Cloud service with enterprise controls and partner models.
Sources read for this page