Overview
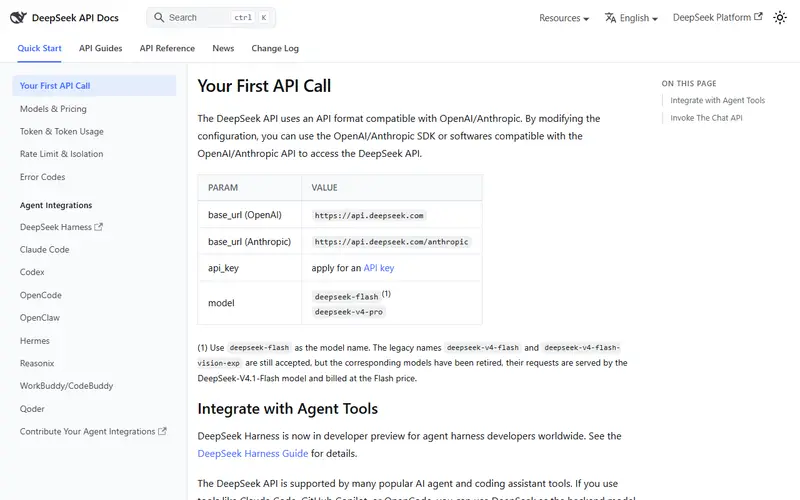
DeepSeek sells API access to its own models: deepseek-flash (DeepSeek-V4.1-Flash, with vision) and deepseek-v4-pro (DeepSeek-V4-Pro-0813). Both offer a 1M-token context, up to 384K output tokens, thinking and non-thinking modes, tool calls and JSON output. The API accepts OpenAI-format requests and also has an Anthropic-format base URL, so many existing SDKs work with a URL change.
Pricing has two twists. Cache hits are extremely cheap ($0.006 per million input tokens on Flash at peak), which rewards long, stable system prompts. And every price halves outside peak hours, which are 01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays, so scheduled batch jobs can run at off-peak rates.
The account is prepaid: you top up a balance and usage is deducted from it, with any granted balance used first. There is no published free tier. Limits are expressed as concurrent requests rather than tokens per minute.
Pricing and plans
| Plan | Price | What you get |
|---|---|---|
| deepseek-flash (peak) | $0.30 in / $1.20 out per 1M | Cache-hit input $0.006; supports vision |
| deepseek-flash (off-peak) | $0.15 in / $0.60 out per 1M | Cache-hit input $0.003 |
| deepseek-v4-pro (peak) | $1.32 in / $3.96 out per 1M | Cache-hit input $0.044; no vision |
| deepseek-v4-pro (off-peak) | $0.66 in / $1.98 out per 1M | Cache-hit input $0.022 |
What it does
- Off-peak pricing
- All token prices halve outside 01:00-04:00 and 06:00-10:00 UTC on weekdays.
- Context caching
- Automatic cache hits billed at about 2% of the cache-miss input price.
- OpenAI and Anthropic formats
- Separate base URLs accept OpenAI-style and Anthropic-style requests, plus a Responses API.
- 1M-token context
- Both models accept 1M tokens of context and up to 384K output tokens.
- Thinking modes
- Thinking mode is the default and can be switched off per request.
Strengths and limitations
Strengths
- Low per-token prices, especially off-peak and on cache hits.
- Prepaid balance means spend cannot exceed what you topped up.
- Drop-in compatibility with OpenAI and Anthropic request formats.
Limitations
- No free tier; the balance must be topped up before use.
- Prices double during weekday peak windows.
- Only DeepSeek's own two current models are offered.
- V4 Pro does not support image input.
- DeepSeek states it may adjust prices and advises checking the pricing page regularly.
Who it suits
Good for
- Batch jobs that can be scheduled into off-peak hours
- Agents that resend long, cacheable context
- Budget-limited side projects that can prepay a small balance
Look elsewhere if
- Teams with data-residency rules that exclude a China-based provider
- Workloads that need several model families behind one API
Pricing history
-
DeepSeek V4 Pro kept after planned end date
DeepSeek says it will keep providing DeepSeek V4 Pro after 2026-09-14, with billing unchanged, in response to user demand. Source ↗
-
DeepSeek-V4.1-Flash launched with lower prices
Announced 2026-09-10: DeepSeek-V4.1-Flash released and API prices reduced accordingly; deepseek-flash is now $0.30 in / $1.20 out per 1M at peak. Legacy deepseek-v4-flash names are served by V4.1-Flash at the Flash price. Source ↗
-
DeepSeek adopts peak and off-peak pricing
Announced 2026-08-13 with DeepSeek-V4-Pro GA: prices now have peak and off-peak rates, with off-peak (outside 01:00-04:00 and 06:00-10:00 UTC on weekdays) at half the peak price. Source ↗
-
DeepSeek V4 released; legacy model names retired
Announced 2026-04-24: V4 Pro and Flash models introduced, and the legacy deepseek-chat and deepseek-reasoner names were set to be discontinued three months later. Source ↗
Alternatives to DeepSeek API
| Tool | From | Free option | Stages |
|---|---|---|---|
| DeepInfra Inference provider (open-weight models) | Usage-based | ||
| Scaleway Generative APIs Inference provider (EU-hosted open-weight models) | Usage-based | ||
| Kimi API (Moonshot AI Open Platform) AI model API (model maker) | Usage-based | ||
| Novita AI Inference provider (open-weight models) | Usage-based | ||
| Gemini API AI model API (model maker) | Usage-based | Free tier | |
| Mistral API (Mistral Studio) AI model API (model maker) | Usage-based | Free tier |
Questions
When is DeepSeek API off-peak pricing?
Off-peak is every hour except 01:00-04:00 and 06:00-10:00 UTC, Monday to Friday. Off-peak prices are half the peak prices.
How much does deepseek-flash cost?
On 2026-09-29, peak prices were $0.30 per 1M cache-miss input tokens, $0.006 per 1M cache-hit input tokens and $1.20 per 1M output tokens; off-peak is half.
Does the DeepSeek API work with the OpenAI SDK?
Yes. It uses an OpenAI-format base URL, and there is also an Anthropic-format endpoint.
Sources read for this page